Estimated reading time: 13 minutes
Key Takeaways
- Using citywide population as a benchmark for police stop data is one of the most misleading measures available. It doesn’t account for where crime is concentrated, where officers are deployed, or who actually comes into contact with police.
- Ratcliffe and Hyland identified nine different benchmarks for measuring racial disparity in stops, ranging from citywide population to NIBRS suspect data filtered for violent crime only.
- The choice of benchmark dramatically changes the result. In Philadelphia’s 2022 data, the odds ratio for Black versus White vehicle stops ranged from 4.4 (citywide population) to 0.57 (violent crime suspect data), with White drivers actually more likely to be stopped under the most crime-specific measures.
- No single benchmark will satisfy everyone, but the study suggests Benchmark 7 (NIBRS suspect data, all crime) offers the best combination of community-sourced data, resistance to arrest bias concerns, and a large enough sample to be meaningful.
In 2022, Philadelphia’s stop data looked damning on its face: Black residents were 4.4 times more likely to be stopped by police than White residents. That’s a ratio that’s hard to argue with at a city council meeting, a community forum, or a press conference.
Except, what if the comparison itself was the problem?
Not the stops. Those happened. The question is what those stops get compared to. Because when you dig into how that 4.4 number was calculated, it comes down to a choice that seems completely reasonable on the surface and is how it has always been done: dividing stop counts by the city’s overall racial population. It makes intuitive sense. Of course you’d compare stops to who lives there. And according to a 2025 study by Jerry Ratcliffe of the University of Pennsylvania and Shelley Hyland of the Bureau of Justice Statistics, it’s also potentially the most misleading method available.
Ratcliffe isn’t a fringe voice on this. He’s one of the most cited criminologists working on policing and place, and his work on hot spot policing and crime concentration has shaped how departments think about proactive enforcement for three decades.
The Study: What Researchers Found About Police Stops
Ratcliffe and Hyland’s paper, “Police Stops and Naive Denominators,” sets out to answer a deceptively simple question: if you’re going to measure racial disparity in police stops, what are you actually comparing stops to?
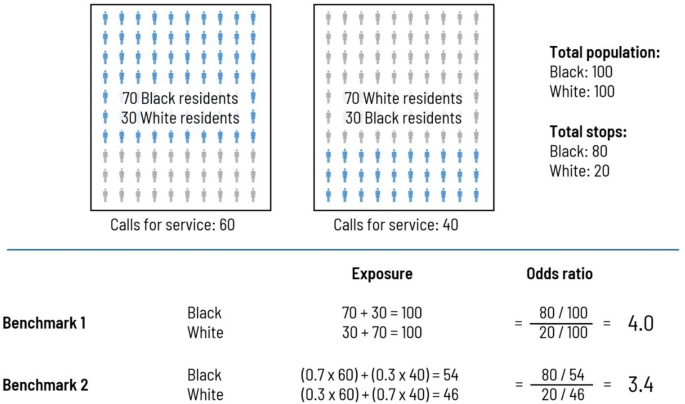
The denominator (the bottom number in your ratio) represents the group potentially exposed to police contact. That’s not a neutral choice. It depends entirely on what kind of stop you’re measuring, where police are deployed, and what priorities a city has handed its department.
Think about it. Pedestrian stops tend to involve people who live nearby, but that changes completely in a business district, a tourist corridor, or an entertainment zone. Vehicle stops skew toward people who can afford cars. And neither measure accounts for where a city has told its officers to be, which calls are pulling them away from proactive work, or which specialized units are working which areas.
Citywide population (the go-to for most media coverage and a fair amount of academic work) captures none of that. It treats everyone in the city as equally exposed to police contact, regardless of where they live, where they go, or what’s happening in their neighborhood.
For their analysis, Ratcliffe and Hyland used Philadelphia’s 2022 pedestrian and vehicle stop data: 133,448 total stops, with 94,552 (70.9%) involving Black residents and 18,867 (14.1%) involving White residents. Just over 90% were vehicle stops. They then calculated racial disparity across nine different benchmarks, and the results didn’t just vary. They told completely different stories.
The Math: A Quick Word on Odds Ratios
Before we get into the benchmarks, a note on how disparity is measured here: odds ratios.
If that phrase makes you want to close the tab, just hold on for one moment please! Trust me, it’s way simpler than it sounds.
An odds ratio compares the likelihood of something happening to one group versus another. An odds ratio of 1.0 means both groups are equally likely to be stopped. An odds ratio above 1.0 means the first group (in this case, Black residents) is more likely to be stopped. Below 1.0, and the second group (White residents) is more likely.
Here’s a concrete example. Say your city has 100 Black residents and 50 White residents. Police make 10 stops involving Black residents and 2 stops involving White residents. The stop rate for Black residents is 10/100 = 0.10. The stop rate for White residents is 2/50 = 0.04. The odds ratio is 0.10 / 0.04 = 2.5. That means Black residents are 2.5 times more likely to be stopped than White residents, relative to their share of the population.
Now swap the population denominator for something more precise (say, only residents who live in neighborhoods where the department actually deploys patrol) and that 2.5 might become 1.8. Or 1.2. Or, depending on your benchmark, it might flip entirely.
That’s the whole argument. The denominator changes the answer.
9 Benchmarks for Measuring Racial Disparity in Police Stops
Ratcliffe and Hyland tested nine. Here’s what each one measures, how it performed in Philadelphia, and when it makes sense to use it.
Benchmark 1: Overall City Population
This is the standard. Take the number of race-specific stops, divide by the race-specific share of the citywide population.
In Philadelphia in 2022: odds ratio of 4.442 for vehicle stops. Black residents were 4.4 times more likely to be stopped than White residents.
This is the number that shows up in news coverage. It’s also, per Ratcliffe and Hyland, “clearly divorced from the realities of where police officers concentrate their time.” Low-crime neighborhoods contribute large population shares but generate minimal police activity. Counting those residents as equally exposed to stops is an assumption that doesn’t hold up.
**When to use it** Possibly for broad demographic transparency reports. But more importantly, critics and journalists will fall back on this ratio because it’s the most familiar. Know what it is, know how it’s calculated, and be prepared to explain why it doesn’t tell the whole story.
Benchmark 2: Calls for Service by Census Tract
Instead of citywide population, this uses where calls for service (CFS) from the public are concentrated (mapped to census tracts) and adjusts by the racial composition of each tract.
In 2022, Philadelphia logged 1,533,973 calls, with 98.9% mappable to a census tract. The weighted Black population equivalent was 650,020; White was 412,806.
Vehicle stops odds ratio: 3.276. Pedestrian stops: 2.481.
Still elevated, but meaningfully lower than Benchmark 1. The logic: residents in high-CFS areas are simply more exposed to police, because that’s where officers are required to spend time. Ignoring that exposure misattributes enforcement patterns as bias.
**When to use it** For agencies that want to account for where police are actually called, without getting into complex weighting. A solid starting point for most general-purpose analysis.
Benchmark 3: CFS Weighted by Officer Count and Call Duration
Same as Benchmark 2, but accounts for how many officers respond and how long they’re on scene. Because a domestic disturbance that ties up four officers for 90 minutes is not the same police exposure as a noise complaint cleared in 10.
Vehicle stops odds ratio: 2.828. Pedestrian stops: 2.142.
**When to use it** When your agency wants a more precise picture of how officer-hours are distributed across the city. Requires CAD data with officer count and call duration attached.
Benchmark 4: Priority One Calls Only (Weighted as in Benchmark 3)
Filters the Benchmark 3 data to include only the most urgent calls (person with a gun, robbery in progress, person screaming) — the calls departments typically direct officers to prioritize and be positioned around.
Vehicle stops odds ratio: 2.396. Pedestrian stops: 1.814. For pedestrian stops, the difference between Black and White stop rates is small enough that it could reasonably be explained by chance.
**When to use it** For patrol units specifically tasked with violent crime response and hotspot coverage. If your department has issued directives to focus on high-crime areas, this benchmark reflects those priorities more honestly than a citywide comparison.
Benchmark 5: Part 1 Violent Crime by Census Tract
Replaces CFS with reported serious violent crime (UCR Part 1 offenses), mapped to census tracts and adjusted by racial composition. There were 15,154 such incidents in Philadelphia in 2022, with 98.4% mappable.
Vehicle stops odds ratio: 2.429. Pedestrian stops: 1.840.
**When to use it** When your department is explicitly prioritizing violent crime. This benchmark reflects where violent crime happens, not just where police happen to be. Ratcliffe and Hyland note this is probably the most reflective benchmark for agencies that have issued place-based violent crime directives, as Philadelphia did in 2024 when it declared a public safety crisis and surged resources to 10 of its 20 police districts accounting for 78% of shooting victims.
Benchmark 6: NIBRS Arrestee Data, All Crime
Here the approach shifts entirely. Instead of spatial data, this uses person-level information: specifically, the racial characteristics of arrestees reported through NIBRS. Philadelphia had 137,881 incidents with 18,864 reported arrestees. Black arrestees: 10,591. White arrestees: 2,756.
Vehicle stops odds ratio: 1.343. Pedestrian stops: 1.017 — essentially no disparity at the pedestrian stop level.
The disparity drops sharply. But this benchmark comes with a built-in criticism: arrestee data may itself reflect bias. If officers are more likely to arrest Black suspects than White suspects for comparable conduct, then using arrest data as a baseline bakes that potential bias into the denominator.
**When to use it** With caution. Better suited as one of several benchmarks rather than a standalone measure.
Benchmark 7: NIBRS Suspect Data, All Crime (Excluding Arrest-Associated Offenders)
This is the study’s strongest candidate for broad departmental use. It uses NIBRS offender data but filters out offenders whose description came in connection with an arrest, keeping only those identified by victims or through warrant-based arrests. The idea is to get suspect descriptions that come from the community, not from officer discretion.
Of 137,881 incidents, 38,735 suspects (28.1%) met this criterion. Black suspects: 27,402. White suspects: 5,761.
Vehicle stops odds ratio: 1.085. Pedestrian stops: 0.821 — White pedestrians are slightly more likely to be stopped than Black pedestrians under this benchmark.
**When to use it** For agencies seeking a community-sourced benchmark that reduces the influence of officer arrest bias. Ratcliffe and Hyland suggest this may be the most defensible general-purpose denominator. It has a reasonably large sample, it’s grounded in victim and witness reporting rather than enforcement decisions, and it connects to operational reality.
Benchmark 8: NIBRS Arrestee Data, Violent Crime Only
Benchmark 6, filtered to serious violent offenses only: murder, manslaughter, rape, robbery, aggravated assault. Just 3,933 arrestees. Black: 2,742. White: 441.
Vehicle stops odds ratio: 0.830. Pedestrian stops: 0.629.
The disparity flips. White residents are now more likely to be stopped than Black residents.
**When to use it** For units specifically targeting serious violent crime offenders. But the sample size is small enough to generate skepticism, and Benchmark 8 inherits Benchmark 6’s bias concern.
Benchmark 9: NIBRS Suspect Data, Violent Crime Only
Benchmark 7, filtered to violent crime suspects only. 7,908 suspects. Black: 6,036. White: 670.
Vehicle stops odds ratio: 0.573. Pedestrian stops: 0.434.
The disparity flips here too, and flips more dramatically. But the sample is relatively small (6,706 suspects), and the authors flag that limitation directly.
**When to use it** For intelligence-led units targeting serious repeat offenders, with awareness that the small sample makes this vulnerable to statistical instability.
What This Means For Your Agency
Let’s be direct about something first: none of this means racial disparities in police stops don’t exist. Even the most operationally grounded benchmarks (Benchmarks 4 and 5) still show Black residents are roughly twice as likely to be stopped as White residents. That’s worth taking seriously, not explaining away.
What the study does is give agencies better tools to understand what they’re actually measuring and to push back when the measurement is clearly wrong.
If your department is stuck with Benchmark 1 comparisons (stops divided by citywide population) here are three things you can do.
Know your operational context. If your department has issued directives to focus patrol resources on high-crime areas, violent crime hotspots, or specific priority call types, that context matters. Benchmark 5 (violent crime by census tract) or Benchmark 4 (priority CFS) will reflect your department’s actual mission better than a citywide headcount.
Build the data infrastructure to run multiple benchmarks. The spatial benchmarks (2 through 5) require geocoded CFS data mapped to census tracts. The NIBRS benchmarks (6 through 9) require your department to be reporting to NIBRS and to have access to that data at the incident level. Neither of these is exotic, but they require deliberate setup. If your department doesn’t have this infrastructure, now is the time to build it.
Use multiple benchmarks together. No single benchmark will satisfy every critic, and Ratcliffe and Hyland don’t claim otherwise. What they do argue is that presenting multiple benchmarks side by side (with honest explanations of what each one measures and why) gives your community a more accurate picture than a single ratio ever could. It also demonstrates that your agency understands the complexity, which is its own form of credibility.
For traffic units specifically, the authors acknowledge that none of these benchmarks fit perfectly, and point to other research suggesting the day/night stop ratio and at-fault accident composition as better alternatives for traffic enforcement analysis.
Final Thoughts
The Philadelphia number (4.4 times more likely) didn’t change. What changed was the question we were asking it to answer.
Ratcliffe and Hyland put it plainly: “Benchmark 1 is clearly divorced from the realities of where police officers concentrate their time.” That’s not a defense of any individual stop. It’s a methodological argument that the standard denominator, the one most commonly used and most frequently cited, is the worst available option.
Departments that understand this aren’t trying to hide something. They’re trying to measure the right thing. And in 2024, when Philadelphia surged officers to 10 of its 20 police districts accounting for 78% of shooting victims, measuring those officers’ activity against a citywide population benchmark wouldn’t have captured what was actually happening, or why.
One caveat worth naming: this study measures whether stops occurred, not the reasons behind them or their outcomes, so it speaks to the measurement question, not to whether any individual stop was justified.
The math will keep showing up. But the agencies that take the time to understand what they’re measuring, and explain it clearly with evidence, will be the ones that can actually have an honest conversation about what their data means.
Enjoyed this post?
Get more research translated into plain language delivered straight to your inbox.
Subscribe below and let me know which topics you want to hear more about. It only takes a minute.
If you found this helpful, share it with your team or on your socials. It helps more people make sense of research that matters.

 English